APIs are contracts: designing integrations that survive change
Integrations fail slowly, then all at once. Treating every API as a contract — explicit, versioned and observable — keeps systems talking as they evolve.
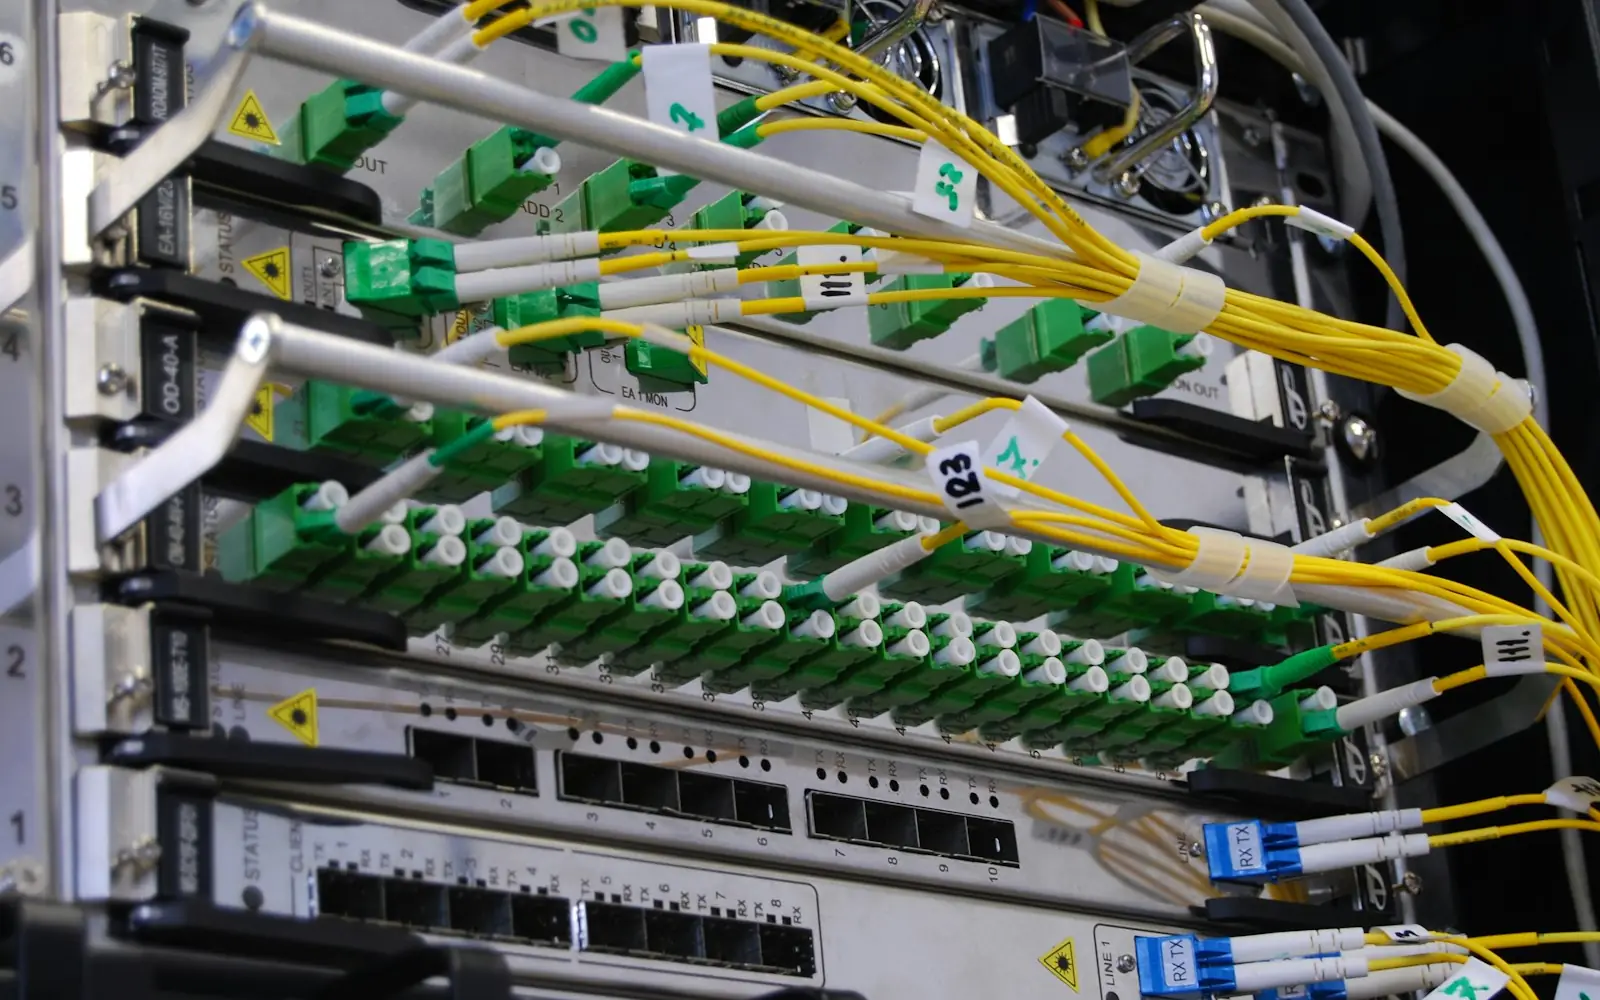
Very few business applications live alone. They exchange data with accounting software, payment providers, suppliers, government platforms and each other. Each of those connections is an API — and each one is a promise between two systems that were built by different people, at different times, for different reasons.
Think in contracts, not endpoints
An endpoint is a technical detail. A contract is a business agreement: when you send me an order in this shape, I will confirm it, reject it with a reason, or tell you I'm unavailable. Writing that contract down — the fields, their meaning, the error cases — is the most useful integration work there is.
A good contract answers questions like:
- Which fields are required, and what does each one mean in business terms?
- What happens when the same request is sent twice?
- How are errors described, and which ones can be retried?
- How will changes be announced, and how long will old versions keep working?
Most integration bugs are not coding errors. They are two teams with different understandings of the same word.
Design for the unhappy path
Networks fail, partners go down for maintenance, and data arrives in shapes nobody expected. Robust integrations assume this from the start:
- Idempotency: repeating a request never creates duplicate orders or payments.
- Timeouts and retries with limits, so one slow partner cannot freeze your system.
- Queues for work that doesn't need to happen instantly.
- Clear error states that a human can understand and resolve.
Version deliberately
Changing an API is inevitable. Breaking its consumers doesn't have to be. Adding fields is usually safe; renaming or removing them is not. When a breaking change is needed, a new version running alongside the old one — with a clear retirement date — turns a crisis into a planned migration.
A checklist before connecting two systems
Before we write the first line of integration code, we want clear answers to a short list of questions — usually in a shared document both teams can edit:
- Ownership: which system is the source of truth for each piece of data, and which one only keeps a copy?
- Direction and timing: is data pushed as events happen, pulled on a schedule, or both? How fresh does it need to be?
- Identifiers: how does each side refer to the same customer, order or product? Mapping IDs is where many integrations quietly break.
- Volumes: how many records per day, and what is the peak? A design that works for a hundred orders may not work for a hundred thousand.
- Security: how are requests authenticated, which data is sensitive, and who can rotate credentials?
- Failure handling: when something goes wrong at 2 a.m., who is alerted, and what can they safely retry?
None of these are exotic. But answering them up front turns an integration from a recurring source of incidents into infrastructure nobody has to think about.
Make it observable
Finally, an integration you cannot see is an integration you cannot trust. Logging each exchange with a correlation identifier, tracking error rates and alerting on unusual patterns means problems are noticed by the team — not reported by a customer.
Working on something similar?
We help companies turn problems like this one into working products. Tell us what you’re dealing with.